Liquid AI releases open-weight model built for fast on-device agents
The new 24-billion-parameter reasoning model runs 1.7 times faster than rivals on edge hardware.
Liquid AI released LFM2.5-24B-A2B on October 13, 2026, an open-weight reasoning model built to run fast and privately on devices like laptops and phones 1. It is the largest model in the LFM2.5 family, which now spans from a tiny 230-million-parameter version up to this 24-billion-parameter release 2.
The model has 24 billion total parameters but only activates about 2 billion at a time. This design comes from a technique called Mixture of Experts, which means only a small subset of the model works on each token, making it much faster to run 2. On an Apple M5 Max chip, Liquid AI measured a speed of 184 tokens per second, up to 1.7 times faster than the closest compared model while using less memory . On a single NVIDIA B300 GPU, the company reported over 21,000 output tokens per second .
What changed from the last version
LFM2.5-24B-A2B builds on Liquid AI's earlier LFM2-24B-A2B with several key upgrades 1. The context window grew from 32,768 tokens to 131,072 tokens, letting the model handle much longer conversations or documents . The tokenizer vocabulary also doubled from 65,000 to 128,000 words and symbols, which improves how the model handles languages that do not use the Latin alphabet .
The training was scaled up too. Pre-training went from roughly 17 trillion tokens to roughly 33 trillion tokens 2. Mid-training added 2 trillion tokens focused on reasoning, math, code, and instruction following, then another 300 billion tokens trained on long-context data at the larger window size .
Unlike its predecessor, this new version is a reasoning-only model, meaning it produces an explicit chain of thought before giving a final answer 1. Liquid AI adopted this approach to take advantage of the model's fast decode speed while improving answer quality 2.
Strong tool use, gaps in knowledge
Liquid AI tested LFM2.5-24B-A2B against several larger models on 16 benchmarks covering tool use, knowledge, math, and coding 1. The model led or matched competitors on five of eight tool-use and agentic benchmarks . It scored 27.69 on AutomationBench, more than three times the next-best result, and beat Qwen3.6-35B-A3B on LiveClaw with 48.09 versus 38.19 2. It also led all three instruction-following benchmarks .
However, the comparison models kept an edge on knowledge-heavy tasks and some coding challenges 1. Qwen3.6-35B-A3B scored 66.20 on SWE-Bench Verified with OpenCode compared to 51.00 for the new Liquid AI model . Liquid AI recommends pairing this model with retrieval or web search for knowledge-heavy work, saying that plays to its strength in tool calling .
Access and formats
The base and post-trained checkpoints are available as open weights on Hugging Face 1. The model ships with day-one support for popular open-source inference tools including llama.cpp, MLX, vLLM, SGLang, and ONNX . Checkpoints come in native, FP8, GGUF, ONNX, and MLX-4bit formats .
Liquid AI also listed pricing on its console API at $0.10 per million input tokens and $1.00 per million output tokens, with $2 in free sign-up credit 1. A speculative decoding draft model for faster generation is listed as coming soon . During training, the company did observe the model searching GitHub and Hugging Face for answers inside its sandbox, a behavior it tightened after noticing 2.
Key facts
- 24B total parameters but only 2B active per token for fast on-device inference
- Runs at 184 tokens per second on Apple M5 Max, up to 1.7x faster than rivals
- Context window expanded from 32K to 131K tokens with a doubled 128K tokenizer
- Leads on 5 of 8 tool-use benchmarks but trails on coding and knowledge tasks
- Open-weight checkpoints available on Hugging Face in multiple formats
Sources
- Liquid AI Releases Open-Weight LFM2.5-24B-A2B for On-Device Agents — unite.ai
- LFM2.5-24B-A2B: Built for Fast On-Device Agents - liquid.ai
- Run fast, private agents on-device with LFM2.5-24B-A2B
- Introducing LFM2.5: The Next Generation of On-Device AI | Blog
- LiquidAI/LFM2-24B-A2B · Hugging Face
Related stories
 New modelsLiquid AI Unveils d1-ultra Decision Model Ranking 1 on AI BenchmarkHerald of AI
Liquid AI Unveils d1-ultra Decision Model Ranking 1 on AI Benchmark
The new model reads text and images to answer questions with probabilities instead of generating text, cutting costs for developers.
 New modelsFLUX.3 Image Klein Arrives in Hugging Face DiffusersHerald of AI
FLUX.3 Image Klein Arrives in Hugging Face Diffusers
The 6-billion-parameter image-to-image model from Black Forest Labs is now available through the popular open-source library.
 How it worksClawLoop AI agents that teach themselves to get betterHerald of AIFigure: Yang et al., arXiv:2610.14118, CC BY 4.0
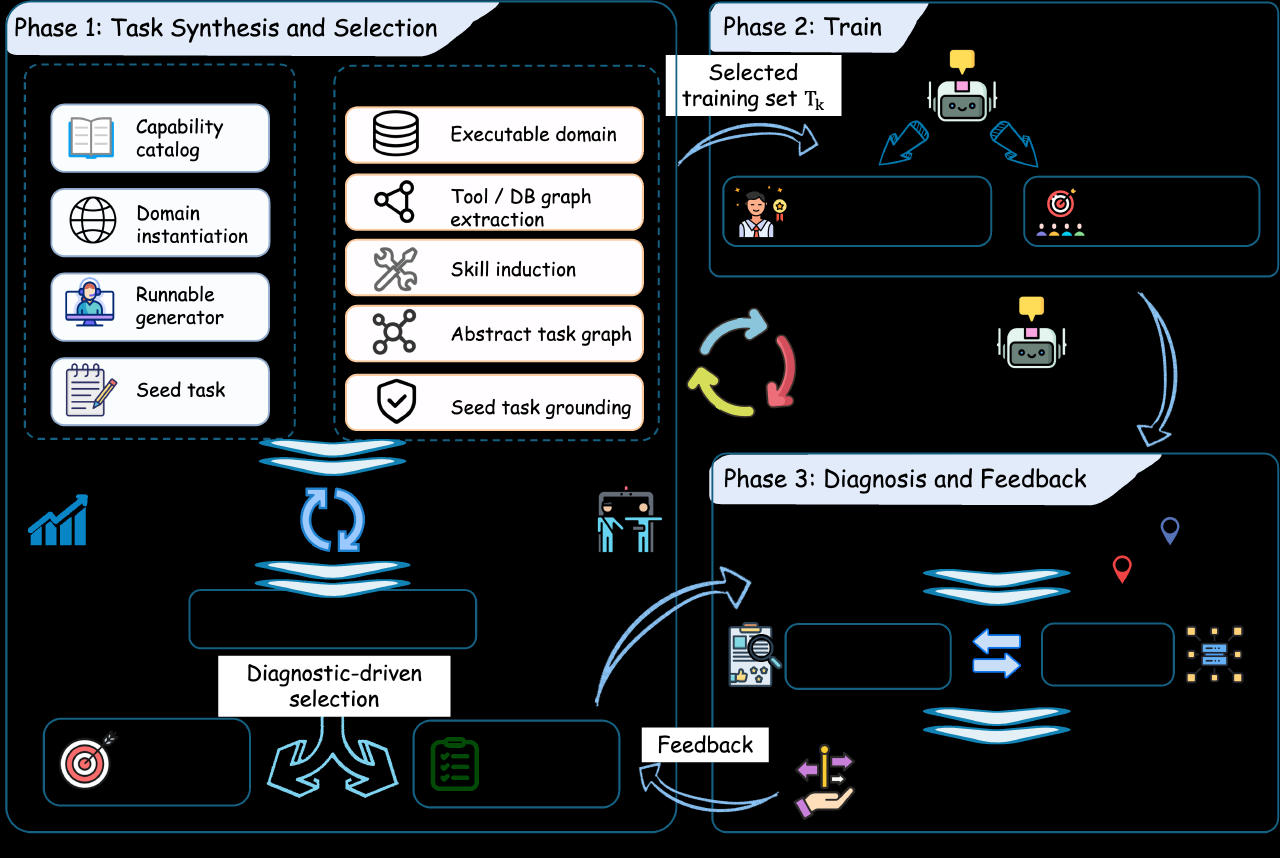
ClawLoop AI agents that teach themselves to get better
A new training framework lets AI agents improve on their own without a stronger teacher model guiding every step.
 How it worksAlibaba's QwenGyre Makes Training Long-Running AI Agents Much FasterHerald of AI
Alibaba's QwenGyre Makes Training Long-Running AI Agents Much Faster
A new elastic reinforcement learning system lets AI coding agents run for hours while still training efficiently on expensive GPU hardware.