Reka Unveils Rho-1 A Single AI Model That Generates Video and Controls Robots
The new 19-billion-parameter model replaces multi-model pipelines by understanding, creating, and reasoning across text, images, video, and robotic actions all at once.
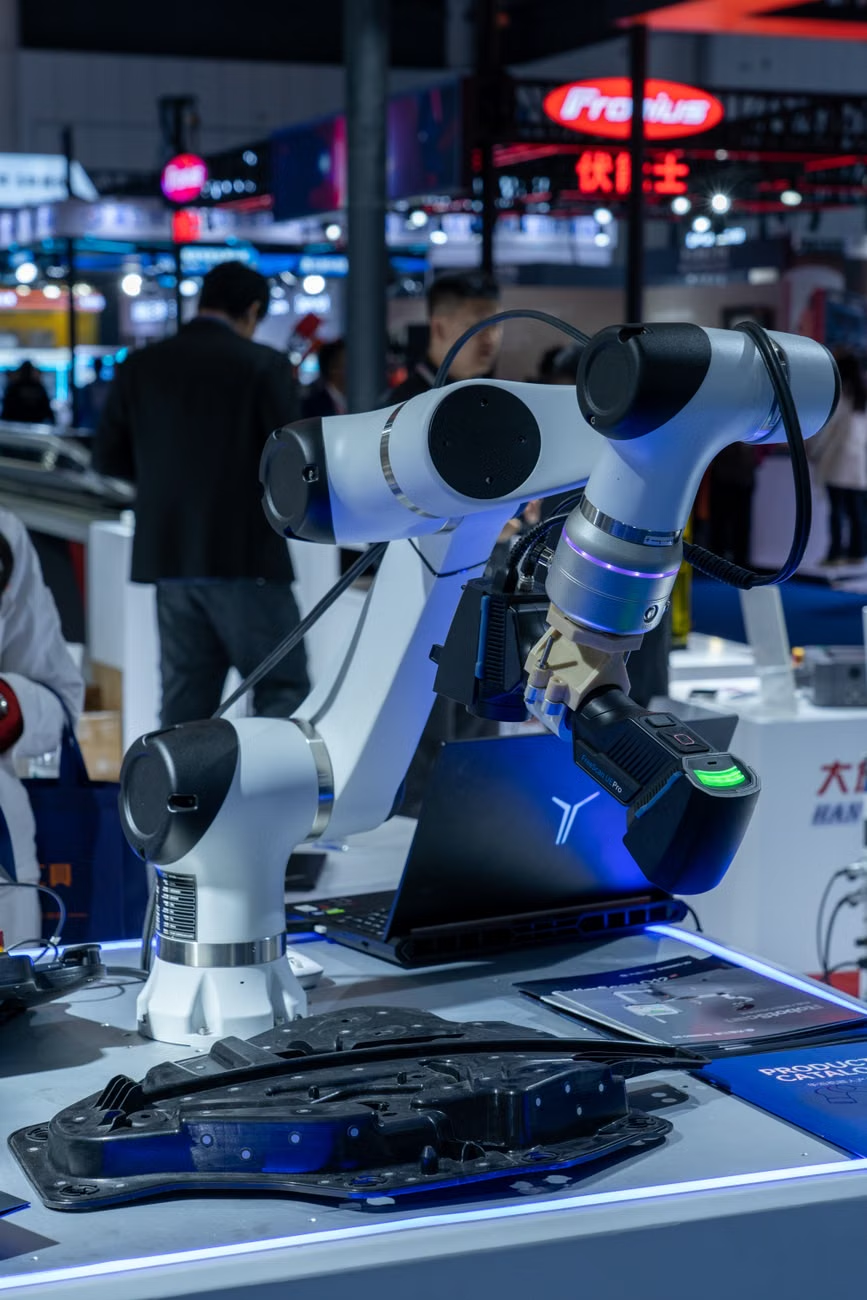
Reka has released a research preview of Rho-1, a 19-billion-parameter "omni-reasoning" model trained entirely from scratch. It is one neural network that can understand and create text, images, and video, reason about them, and even output robotic commands -- all without switching between different specialized models 1.
Why This Matters
Most multimodal (meaning "able to handle multiple types of data") AI systems today work like assembly lines. A central model plans a task, then hands it off to separate specialists for images, video, or detection. Each handoff adds delay, and each specialist only sees a narrow slice of the problem 1.
Rho-1 removes those handoffs entirely. Text, images, video, and robotic actions are all treated as tokens -- the basic building blocks the model works with -- inside one shared context window. In one unedited demo, the model drew a lighthouse, boxed it, animated it, edited the video into a snowstorm scene, and explained the difference -- all in five turns and using no second model 1.
How It Works
Rho-1 uses two expert streams inside every layer of its neural network, but they share one memory system called a KV cache (short for key-value cache, which stores information the model has already processed so it does not need to recompute it) 1.
The understanding stream handles language and visual parsing, while the generation stream turns compressed data representations called latents into images and video. When the model needs to produce pixels, the understanding stream sends a special handoff token, and the generation stream renders from the full accumulated state 1.
Training combines next-token prediction (predicting the next piece of data in a sequence) for text and symbolic reasoning with flow matching for continuous outputs like images and video 1.
This means bounding boxes come out as coordinate tokens instead of needing a separate detector, and a video's first frame reuses the already-computed image representation instead of encoding it again 1.
Speed and Performance
The base Rho-1 model generates video at about 0.79 times real-time speed, with a watchable stream starting in roughly six seconds 1. Reka measured seven seconds to generate a first clip, compared to an illustrative 13.8 seconds for a multi-agent pipeline using separate models .
A distilled (simplified) variant cuts the denoising steps from 99 down to just eight, with minimal reported quality loss. It produced a 5.3-second clip in about one second 1. In internal tests, it matched the fastest dedicated image models and was the quickest tested model to produce its first text token . Reka notes these are vendor-run tests, not independent benchmarks .
Robotics and World Modeling
Rho-1 streams continuously, clip after clip, and new instructions can enter through the understanding stream and update its state mid-generation 1. In one demonstration, a video of a fork splitting into "bank left" and "bank right" continuations was shown .
For robotics, actions and future frames decode from the same latent state. A simulation episode in the LIBERO environment showed Rho-1 emitting seven action channels 1. To scale past the limited amount of teleoperation (remote control) training data available, Reka also pairs Rho-1 with its Inverse Dynamics Model, which infers control signals from raw video .
Comparison to Other Models
Rho-1's 19B parameters sit between ByteDance's 14-billion-parameter BAGEL (which uses a Mixture of Experts design) and BAAI's 34-billion-parameter Emu3.5 1. Google DeepMind's Genie 3 generates native video at 720p but does not output robotic actions . Unlike some competitors, Rho-1 is not open-weight and is currently only available as a research preview via email request .
Rho-1 was trained on 320 H100 GPUs over three months, and its video output is capped at 672 by 384 resolution 1. There is no public API or pricing yet .
Key facts
- Rho-1 is a 19B parameter model that handles text, images, video, and robotic actions in a single network
- A distilled version cuts denoising from 99 to 8 steps, producing a 5.3-second clip in about 1 second
- Video output is capped at 672x384 resolution
- Trained on 320 H100 GPUs over 3 months
- Available only as a research preview via email; no public weights, API, or pricing yet
Sources
- Reka Releases Rho-1: A 19B Omni-Reasoning Model That Understands, Generates Video and Outputs Robot Actions in One — marktechpost.com
Related stories
 New modelsGoogle's Gemini 4 Argon powers Chrome refactor, beats rivals in intelligence testsHerald of AI
Google's Gemini 4 Argon powers Chrome refactor, beats rivals in intelligence tests
The latest model helped Chrome engineers complete months of work in weeks while climbing the top of benchmark rankings.
 New modelsGoogle's Gemini 4 Argon brings deep physical reasoning to real robotsHerald of AI
Google's Gemini 4 Argon brings deep physical reasoning to real robots
The robotics-focused Gemini 4 Argon model scores 87% on a hard 3D reasoning benchmark and controls Boston Dynamics Spot in real-world manipulation tasks.
 PeopleGoogle's Gemini 4 Argon targets the hardest problems firstHerald of AI▶
Google's Gemini 4 Argon targets the hardest problems first
The new frontier model from Google DeepMind is already helping engineers and scientists tackle months of work in weeks.
 Made with AIByteDance's Fully AI Game Hits Steam With 88% Positive ReviewsHerald of AI
ByteDance's Fully AI Game Hits Steam With 88% Positive Reviews
A xianxia RPG built entirely with AI art, voice, and code is challenging what a \"made with AI\" game can feel like.