NVIDIA Releases Open 120B Nemotron 3.5 Super VL Model
The open-source model combines text, image, video, and coding into one agent-ready system that runs on a single GPU.
What Is Nemotron 3.5 Super VL?
NVIDIA has released Nemotron 3.5 Super VL, an open-source vision-language model built for always-on enterprise agents1. The model has 120 billion parameters in total, but only 12 billion are active for each token it processes. This is possible because it uses a mixture of experts (MoE) design, where many smaller sub-models share the work and only the relevant ones activate for any given input. The system can read text, images, documents, and short video clips, then reason, call external tools, and write code—all in one model. For developers, this means one open checkpoint replaces the need for a separate text model and a separate vision model.
How Does It Work?
The model’s backbone interleaves Mamba-2 layers, MoE layers, and traditional attention layers. Each MoE layer contains 512 routed experts, meaning the system can pick the best specialists for a task on the fly1. A custom vision encoder called C-RADIO processes images, document pages, and video frames, then passes them to the language backbone.
Speed comes from four techniques. Multi-token prediction lets a native drafter propose several words at once, which are verified in a single forward pass. LiLiCorr is a speculative drafter optimized for Blackwell GPUs like the DGX Spark, boosting token generation up to 2.3× faster. NVFP4 is a quantization-aware distillation method that compresses weights and activations to 4-bit precision on Blackwell hardware, while using 4-bit weights with 16-bit activations on other chips. Finally, context reuse (prefix caching) keeps both the attention cache and the Mamba states across different turns of an agent conversation, saving computation1.
Nemotron 3.5 Super VL was distilled from the larger Nemotron 3 Ultra model. The training data covered roughly 26 trillion tokens, followed by about 3.8 million post-training samples and reinforcement learning across dozens of environments1. An extra 10 billion Indic-language tokens were added during continued pretraining to improve multilingual capability.
Performance and Deployment
On reasoning benchmarks, the NVFP4 checkpoint scored 89.90 on GPQA-Diamond, a graduate-level science question set, and 71.07 on SWE-bench Verified, which measures real-world coding ability1. In agent-focused evaluations, Super VL outperformed the older Nemotron 3 Ultra despite having far fewer total parameters: 63.44% on Hermes Bench versus Ultra’s 56.33%, and 87.05% on LangChain evals versus 84.3%
The model is available on Hugging Face, OpenRouter, and ModelScope, and can be run through NVIDIA NIM. Supported runtimes include vLLM, SGLang, and TensorRT-LLM on Blackwell and Hopper GPUs. Local paths such as llama.cpp and Unsloth also work. For production use, Dynamo recipes add key-value-aware routing, which NVIDIA says can serve eight times more users at 50 tokens per second per user while cutting first-token latency by 85%
Early customer results include Scale AI reporting 40× lower inference cost and 5× lower latency for vendor credit processing; Ramp achieving up to 50% higher throughput and expecting 10× lower latency for receipt-to-JSON extraction; and AI21 seeing a 40% accuracy boost on an Alice threat-intelligence task1.
Alongside Super VL, NVIDIA released two smaller edge models: Nemotron 3.5 Bolt 74B-A9B, which targets local agents and fits into 24 GB of memory thanks to native 2-bit quantization, and the tiny Bolt E4B 4GB version, aimed at voice assistants and embedded agents on GeForce RTX, Jetson, and DGX Spark systems.
Key facts
- 120B total parameters, 12B active per token via mixture of experts
- Handles text, images, documents, and video (up to 2‑minute MP4 clips)
- NVFP4 checkpoint runs on a single DGX Spark, H200, H100, or GB200
- Scores 89.90 on GPQA‑Diamond and 71.07 on SWE‑bench Verified
- Two companion edge models: Bolt 74B‑A9B and Bolt E4B 4GB
Sources
- NVIDIA Releases Nemotron 3.5 Super VL, a 120B Open Multimodal Agent Model — marktechpost.com
Related stories
 How it worksHow Echo lets big AI models train faster using ultra-low 4-bit dataHerald of AI
How Echo lets big AI models train faster using ultra-low 4-bit data
A new communication method cuts the data-hauling bottleneck in large AI training by sending just 4 bits at a time, without breaking model quality.
 New modelsNVIDIA launches compact AI model for smarter game NPCsHerald of AI▶
NVIDIA launches compact AI model for smarter game NPCs
A new lightweight language model lets players talk to in-game characters that respond in real time, running locally on consumer hardware.
 How it worksNVIDIA teaches AI agents to bounce back after one bad moveHerald of AI
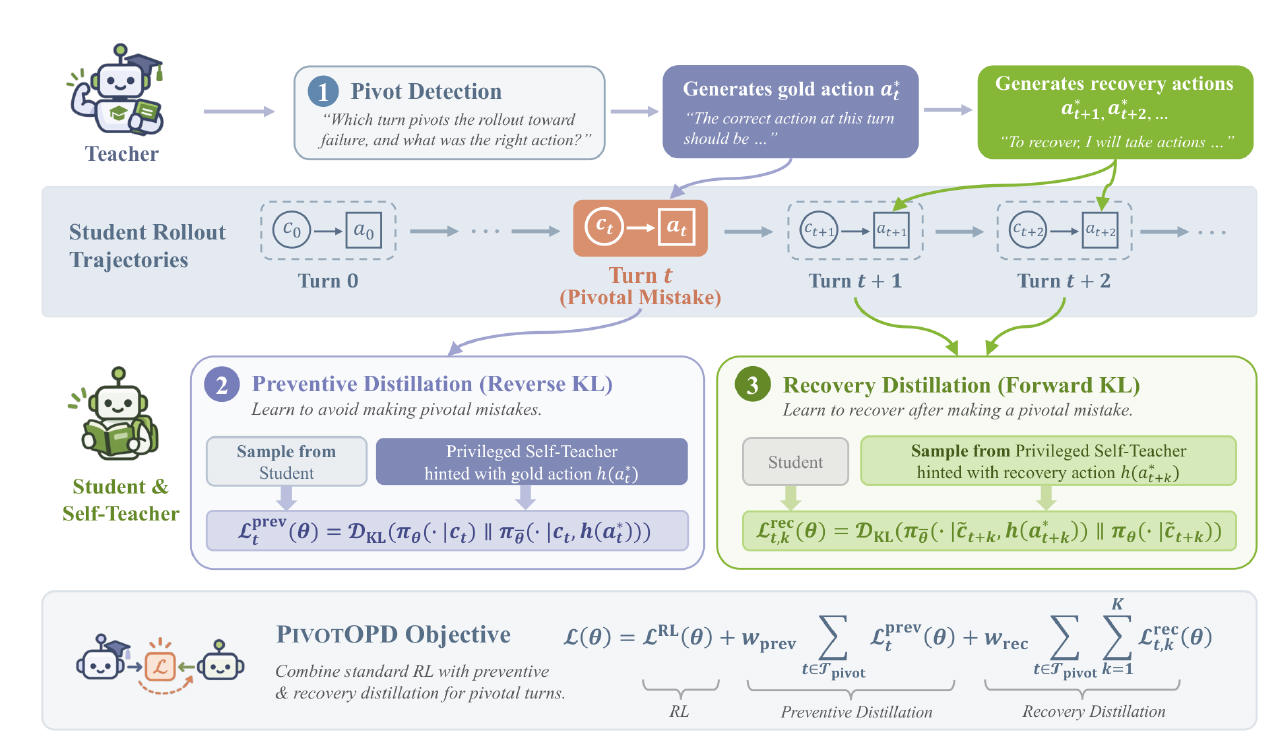
NVIDIA teaches AI agents to bounce back after one bad move
A new training method helps multi-turn AI agents spot their most damaging early mistake and recover from it instead of spiraling.
 How it worksArchitect Launches Liquid Inference, an Auction Marketplace for LLM ComputeHerald of AI
Architect Launches Liquid Inference, an Auction Marketplace for LLM Compute
A financial-tech company is applying exchange-style auction mechanics to LLM inference, letting providers bid for every request.